Semantic Deduplication
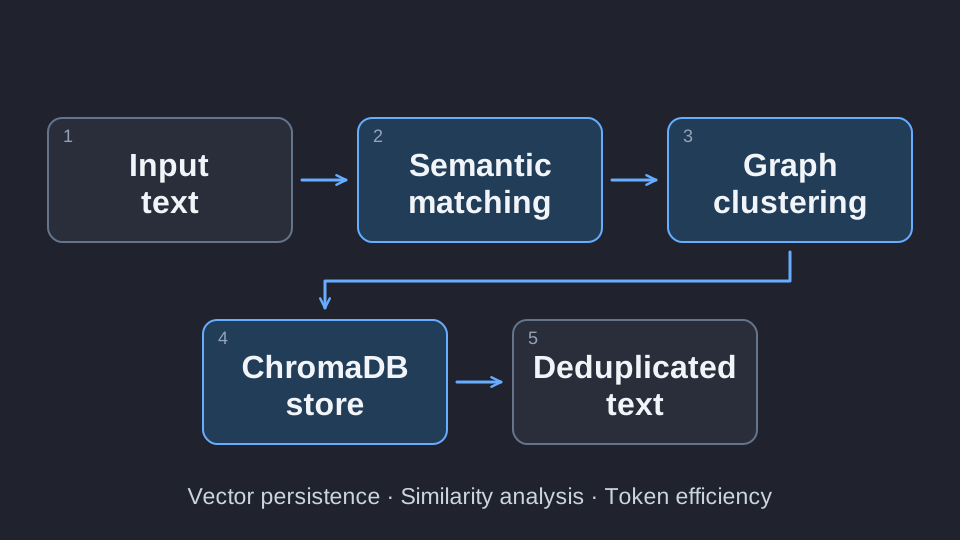
CPU-optimized semantic clustering engine achieving ~34% token reduction for RAG pipelines via SimHash and graph clustering.
Optimization Engine · Role: R&D
Architecture
- SimHash near-duplicate prefiltering
- NetworkX graph clustering
- ChromaDB persistence
Results & scale
- 33.9% character reduction avg
- Fast CPU-based processing
Technology stack
- Python
- NetworkX
- ChromaDB
- SentenceTransformers